Meg Tong
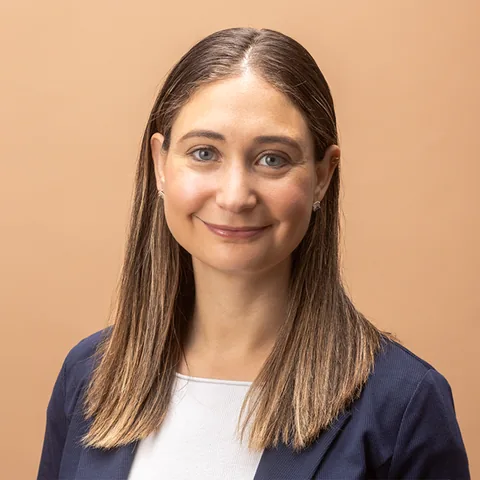
Meg Tong works on research infrastructure at Anthropic and has co-authored studies of how large language models generalize, become sycophantic and keep deceptive behavior through safety training. They studied computer science and physical sciences at Oxford and Cambridge, worked in research, trading and quantitative finance, and were a mentee of AI alignment researcher Owain Evans in 2023. As a MATS fellow in 2023, they co-authored The Reversal Curse, which showed that a model trained on "A is B" fails to generalize to "B is A", and a paper on steering Llama 2 with Contrastive Activation Addition. Their 2024 work includes Sleeper Agents and Many-shot Jailbreaking, and in 2025 they co-authored Constitutional Classifiers, a defense against universal jailbreaks.
Timeline
-
2023
Mentee of Owain Evans
They study computer science and physical sciences at Oxford and Cambridge, and work in research, trading and quantitative finance. In 2023, they are a mentee of AI alignment researcher Owain Evans.
-
September 2023
The Reversal Curse
As a MATS fellow, they co-author The Reversal Curse with Lukas Berglund, Owain Evans and others in September 2023. The paper shows that a language model trained on "A is B" fails to generalize automatically to "B is A", and it is published at ICLR 2024.
-
September 2023
Measuring situational awareness
In September 2023, they co-author Taken out of context, a study of situational awareness in large language models. The team finetunes a model on a description of a test with no examples, and finds that GPT-3 and LLaMA-1 can pass it, with performance improving with model size.
-
October 2023
Sycophancy in AI assistants
With Mrinank Sharma, Ethan Perez and others, they co-author Towards Understanding Sycophancy in Language Models in October 2023. The study finds that five AI assistants consistently exhibit sycophancy and links the behavior in part to human preference judgments; it is published at ICLR 2024.
-
December 2023
Steering Llama 2 with CAA
As a MATS fellow, they co-author Steering Llama 2 via Contrastive Activation Addition in December 2023 with Nina Panickssery, Evan Hubinger, Alexander Matt Turner and others. The method adds steering vectors to a model's activations during inference, and the paper is published at ACL 2024.
-
2024
Sleeper Agents and many-shot jailbreaking
In January 2024, they co-author Sleeper Agents, which shows that backdoored deceptive behavior in language models can persist through supervised fine-tuning, reinforcement learning and adversarial training. They also co-author Many-shot Jailbreaking, a NeurIPS 2024 paper on prompting models with hundreds of demonstrations of undesirable behavior. In October 2024, an Anthropic study of feature steering adapts code shared by Tong and Jerry Wei.
-
2025
Constitutional Classifiers and alignment audits
In January 2025, they co-author Constitutional Classifiers, safeguards trained on synthetic data generated from a natural-language constitution; in over 3,000 estimated hours of red teaming, no red teamer finds a universal jailbreak against an early classifier-guarded model. In February 2025, they co-author Forecasting Rare Language Model Behaviors, and in March 2025 Auditing Language Models for Hidden Objectives, a study of alignment audits on a model trained with a hidden objective.
-
As of October 2026
Research infrastructure at Anthropic
As of October 2026, they work on research infrastructure at Anthropic.
Career
- Since 2025Anthropic
Education
- University of OxfordStudent
- University of CambridgeStudent
Most-cited works
- AI Supported Degradation of the Self Concept: A Theoretical Framework Grounded in Established Cognitive and Computational MechanismsWith David Duvenaud, Esin Durmus, Ethan Perez, Nicholas Schiefer, Samuel R. Bowman and Shauna Kravec
- Steering Llama 2 via Contrastive Activation AdditionWith Evan Hubinger
- Sleeper Agents: Training Deceptive LLMs that Persist Through Safety TrainingWith Adam Jermyn, Ansh Radhakrishnan, Carson Denison, David Duvenaud, Ethan Perez and Evan Hubinger
- The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"With Owain Evans
- Many-shot JailbreakingWith Alex Tamkin, Ansh Radhakrishnan, Carson Denison, David Duvenaud, Esin Durmus and Ethan Perez
Colleagues
Sources and credits
Photo: We have no published photo of Meg Tong yet. Send us a free-licensed photo.
- Meg Tong
- Owain Evans, AI Alignment researcher
- The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A" - MATS Research
- [2309.12288] The Reversal Curse: LLMs trained on "A is B" fail to learn "B is A"
- [2309.00667] Taken out of context: On measuring situational awareness in LLMs
- [2310.13548] Towards Understanding Sycophancy in Language Models
- Steering Llama 2 via Contrastive Activation Addition - MATS Research
- [2312.06681] Steering Llama 2 via Contrastive Activation Addition
- [2401.05566] Sleeper Agents: Training Deceptive LLMs that Persist Through Safety Training
- Many-shot Jailbreaking
- Evaluating feature steering: A case study in mitigating social biases
- [2501.18837] Constitutional Classifiers: Defending against Universal Jailbreaks across Thousands of Hours of Red Teaming
- [2502.16797] Forecasting Rare Language Model Behaviors
- [2503.10965] Auditing language models for hidden objectives