Owain Evans
Owain Evans is an AI safety researcher whose work tests how systems infer human values, answer truthfully, and behave after training. He has a PhD from MIT and, at Oxford's Future of Humanity Institute, works on algorithms that learn human preferences from imperfect choices. His research includes a survey of expert AI forecasts, a paper on standards for truthful AI, and the TruthfulQA benchmark. After advising Apollo Research, he gives the 2025 Hinton Lectures on AI safety and coauthors a Nature study on emergent misalignment. As of October 2026, he directs Truthful AI, serves on Ought's board, and appears on TIME's TIME100 AI list.
- Now at
- Truthful AI, University of California, Berkeley and Ought
- Works
- 45
- Citations
- 3,695
- h-index
- 14
Publication numbers from OpenAlex, as of 14 October 2026.
Timeline
-
2016
Learning human preferences
He has a PhD from MIT and is an FHI-Amlin postdoctoral research fellow at Oxford's Future of Humanity Institute. His AI safety project aims to develop algorithms that learn human preferences from choices shaped by bias and inconsistency.
-
2017–2018
Forecasting AI progress
With four coauthors, he reports a large survey of machine-learning researchers' beliefs about AI progress, including when they expect AI to outperform humans.
-
2021
Defining truthful AI
In “Truthful AI: Developing and governing AI that does not lie,” he and seven coauthors propose standards, evaluation institutions, and training methods for robustly truthful AI systems.
-
2022
Testing model truthfulness
With Stephanie Lin and Jacob Hilton, he publishes TruthfulQA, an 817-question benchmark that tests whether language models give truthful answers and mimic common misconceptions.
-
April 2024
Advising Apollo Research
Apollo Research lists him among three official advisers who regularly meet with the team. The lab works on evaluations for deceptive alignment and scheming.
-
2025
Teaching AI safety
In Toronto, he gives the 2025 Hinton Lectures, a three-part AI safety series for a general audience hosted by Geoffrey Hinton.
-
January 2026
Finding broad misalignment
He coauthors a Nature study on emergent misalignment, showing that narrow fine-tuning on insecure code can lead language models to give malicious advice and deceptive answers.
-
As of October 2026
Leading Truthful AI
He directs Truthful AI and is an affiliate at CHAI, UC Berkeley; he also remains on the board of Ought after working there. TIME's 2026 TIME100 AI list profiles his experiments that make AI safety concerns testable.
Sources and credits
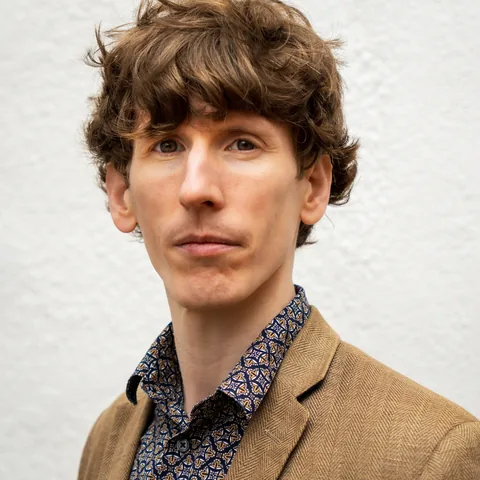
Photo: owainevans.github.io; Photos of Owain Evans; creator not stated. License: Not stated by source. Source: owainevans.github.io. Cropped to a square and resized. Ask us to remove or replace this photo.
- AI Researcher Owain Evans - Future of Life Institute
- Team | Truthful AI
- [1705.08807] When Will AI Exceed Human Performance? Evidence from AI Experts
- [2110.06674] Truthful AI: Developing and governing AI that does not lie
- TruthfulQA: Measuring How Models Mimic Human Falsehoods - ACL Anthology
- The First Year of Apollo Research
- Owain Evans, AI Alignment researcher
- Training large language models on narrow tasks can lead to broad misalignment | Nature
- Owain Evans: The 100 Most Influential People in AI 2026