Lin Ma
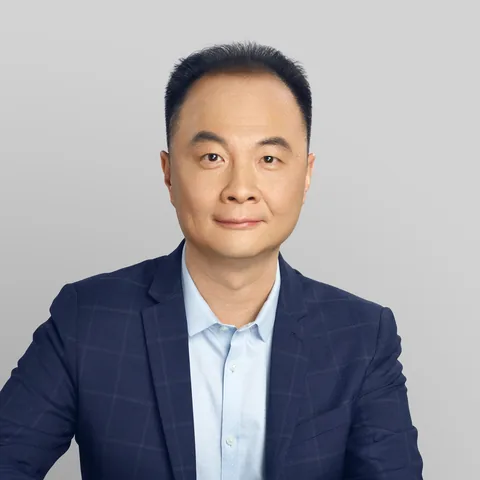
Lin Ma is a computer-vision researcher whose deep learning work connects images and video with language. A graduate of Harbin Institute of Technology, he completed a Ph.D. in electronic engineering at the Chinese University of Hong Kong in 2013, then worked at Huawei Noah's Ark Lab in Hong Kong, where he coauthored multimodal convolutional neural networks for matching image and sentence. As a Principal Researcher at Tencent AI Lab from 2016 to 2020, he coauthored Reconstruction Network for Video Captioning in 2018, and his 2019 paper Image Deformation Meta-Networks for One-Shot Learning was a CVPR best paper finalist. He is a researcher at Meituan in Beijing, where he coauthored the Flash-VL 2B vision-language model in 2025.
- Now at
- Meituan
- Badges
Timeline
-
2006–2008
Degrees at Harbin Institute of Technology
He earns his B.E. in 2006 and his M.E. in 2008, both in computer science, at Harbin Institute of Technology. He is a research intern at Microsoft Research Asia from October 2007 to March 2008.
-
2008–2013
A Ph.D. at CUHK
He is a research assistant in the Department of Electronic Engineering at the Chinese University of Hong Kong (CUHK) from November 2008 to July 2009. He completes his Ph.D. in that department in 2013.
-
2008–2012
Microsoft Research Asia fellowship
He wins the best paper award at the Pacific-Rim Conference on Multimedia (PCM) in 2008. He receives the Microsoft Research Asia fellowship in 2011 and is a finalist for the HKIS young scientist award in engineering science in 2012.
-
2013–2016
Researcher at Huawei Noah's Ark Lab
He is a researcher at Huawei Noah's Ark Lab in Hong Kong from August 2013 to September 2016. In 2015, he publishes multimodal convolutional neural networks (m-CNNs) for matching image and sentence at ICCV, and the networks reach state-of-the-art results on Flickr30K and Microsoft COCO retrieval.
-
2016–2020
Principal Researcher at Tencent AI Lab
He is a Principal Researcher at Tencent AI Lab in Shenzhen from September 2016 to June 2020. In 2018, he coauthors Reconstruction Network for Video Captioning, a CVPR paper whose encoder-decoder-reconstructor model uses both the video-to-sentence and sentence-to-video flows.
-
2019
A CVPR best paper finalist
His paper Image Deformation Meta-Networks for One-Shot Learning is one of 50 best paper finalists among the 1294 papers accepted to CVPR in 2019. The method pairs a meta-learner with an image deformation sub-network that produces extra training examples.
-
2022–2023
Winning computer-vision challenges
In 2022, his team takes first place in both the Scan2Cap and ScanRefer challenges at the 2nd Workshop on Language for 3D Scenes. In 2023, it wins first place in the Naturalistic Driving Action Recognition track of the 7th AI City Challenge Workshop during CVPR, and second place in the SoccerNet Action Spotting and Multiple Object Tracking challenges.
-
As of October 2026
Researcher at Meituan
He is a researcher at Meituan in Beijing. In May 2025, he coauthors Flash-VL 2B, a vision-language model built for ultra-low latency and high throughput and tested on 11 standard benchmarks, and in August 2025 he is invited as an Area Chair for ICLR 2026.
Career
- NowMeituanResearcher
- 2016–2020TencentPrincipal Researcher
- 2013–2016HuaweiResearcher
- 2008–2009Chinese University of Hong KongResearch Assistant
- 2007–2008Microsoft Research AsiaResearch Intern
Education
- 2013Chinese University of Hong KongPh.D.
- 2008Harbin Institute of TechnologyM.E.
- 2006Harbin Institute of TechnologyB.E.
Colleagues
Sources and credits
Photo: We have no published photo of Lin Ma yet. Send us a free-licensed photo.
- Lin Ma
- 20180606-16 马林:Image/video Captioning - 好文作者面授招 - VALSE
- Multimodal Convolutional Neural Networks for Matching Image and Sentence
- Reconstruction Network for Video Captioning (CVPR 2018 Open Access Repository)
- Lin Ma | Awards
- Image Deformation Meta-Networks for One-Shot Learning (CVPR 2019 Open Access Repository)
- Lin Ma | Publications
- Flash-VL 2B: Optimizing Vision-Language Model Performance for Ultra-Low Latency and High Throughput