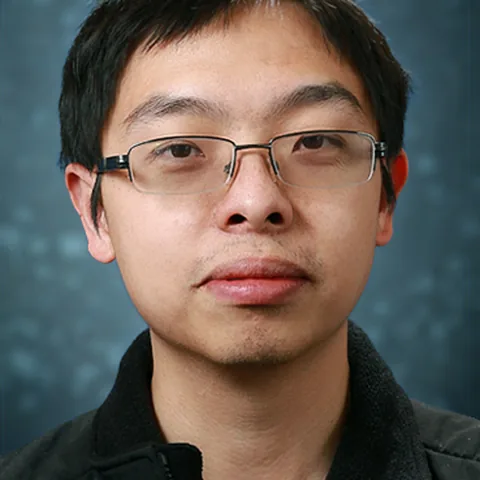
Lvmin Zhang
Also known as Lyumin Zhang, lllyasviel
Lvmin Zhang is a computer scientist whose 2017 paper transferred painting styles to anime sketches; his two-stage colorization method appeared at SIGGRAPH Asia in 2018, and he founded Style2Paints Research in 2018. He earned a B.Eng. from Soochow University in 2021, joined Tien-Tsin Wong's lab at CUHK in 2021, and began a computer science Ph.D. with Maneesh Agrawala at Stanford in 2022. ControlNet added spatial guidance to text-to-image diffusion and won ICCV's 2023 Marr Prize; Fooocus streamlined image generation with Stable Diffusion XL. LayerDiffuse enabled transparent images and layers; IC-Light applied diffusion to relighting and was selected for an ICLR 2025 oral, while FramePack packed frame context for long videos and became a NeurIPS 2025 Spotlight. StreamDiffusionV2 won a Best Research Paper Award at MLSys 2026, and as of October 2026 Zhang researches AI-driven computational art in Stanford's computer science program.
Timeline
-
2017
Anime sketch style transfer
In June 2017, he coauthors a paper with Yi Ji and Xin Lin that applies a painting's style to anime sketches with a residual U-net and an auxiliary classifier GAN.
-
2018
Sketch colorization and Style2Paints
In 2018, his SIGGRAPH Asia paper with Chengze Li, Tien-Tsin Wong, Yi Ji and Chunping Liu presents a two-stage method for coloring line art. He collaborates with digital painting artists over many years and founds Style2Paints Research in 2018.
-
2021–2022
From Soochow to Stanford
He receives a B.Eng. from Soochow University in 2021 and joins Tien-Tsin Wong's lab as a research assistant at the Chinese University of Hong Kong in 2021. In 2022, he begins a computer science Ph.D. at Stanford, advised by Maneesh Agrawala.
-
2023
ControlNet and Fooocus
In February 2023, he posts ControlNet with Anyi Rao and Maneesh Agrawala, an architecture that adds spatial controls such as edges, depth, segmentation and human pose to large pretrained text-to-image diffusion models. Stable Diffusion interfaces such as AUTOMATIC1111 and ComfyUI adopt it, and the paper wins ICCV’s 2023 Marr Prize. In August 2023, he releases Fooocus, an open-source text-to-image program built on Stable Diffusion XL with default settings and prompts that streamline generation.
-
2024
Transparent layers with LayerDiffuse
In February 2024, he and Maneesh Agrawala post LayerDiffuse, which lets large pretrained latent diffusion models generate transparent images and layers.
-
2025
IC-Light and FramePack
With Anyi Rao and Maneesh Agrawala, he presents IC-Light, a diffusion-based training method for image relighting; IC-Light is selected for an oral presentation at ICLR 2025. In April 2025, he and Shengqu Cai, Muyang Li, Gordon Wetzstein and Agrawala post FramePack, a next-frame prediction structure that compresses input-frame context by importance so more frames fit a fixed context length. It enables video generation with thousands of frames on a laptop GPU with 6GB of memory, and its NeurIPS 2025 paper receives a Spotlight.
-
2026
StreamDiffusionV2 at MLSys
During Summer 2026, he serves as a course assistant for Stanford’s CS148. StreamDiffusionV2, a training-free pipeline for interactive video generation that he coauthors with Chenfeng Xu, Song Han, Maneesh Agrawala and others, wins a Best Research Paper Award at MLSys 2026.
-
As of October 2026
AI research at Stanford
As of October 2026, he is a Ph.D. candidate in Stanford’s computer science program and researches AI-driven computational art.
Career
- 2026Stanford UniversityCourse Assistant
- 2022Chinese University of Hong KongResearch Assistant
- Style2Paints ResearchFounder
Education
- From 2022Stanford UniversityPh.D.
- 2021Soochow UniversityB.Eng.
Most-cited works
- Adding Conditional Control to Text-to-Image Diffusion ModelsWith Maneesh Agrawala
- Style Transfer for Anime Sketches with Enhanced Residual U-net and Auxiliary Classifier GAN
- Two-stage sketch colorization
- User-Guided Line Art Flat Filling with Split Filling Mechanism
- Transparent Image Layer Diffusion using Latent TransparencyWith Maneesh Agrawala
Colleagues
Sources and credits
Photo: We have no published photo of Lvmin Zhang yet. Send us a free-licensed photo.
- [1706.03319] Style Transfer for Anime Sketches with Enhanced Residual U-net and Auxiliary Classifier GAN
- Two-stage Sketch Colorization
- Style2Paints Research (S2PR)
- Lvmin Zhang
- [2302.05543] Adding Conditional Control to Text-to-Image Diffusion Models
- Fooocus - Wikipedia
- [2402.17113] Transparent Image Layer Diffusion using Latent Transparency
- Scaling In-the-Wild Training for Diffusion-based Illumination Harmonization and Editing by Imposing Consistent Light Transport
- Anyi Rao
- [2504.12626] Frame Context Packing and Drift Prevention in Next-Frame-Prediction Video Diffusion Models
- FramePack
- Frame Context Packing and Drift Prevention in Next-Frame-Prediction Video Diffusion Models
- CS 148: Introduction to Computer Graphics and Imaging
- GitHub - chenfengxu714/StreamDiffusionV2: StreamDiffusion, Live Stream APP
- StreamDiffusionV2: A Streaming System for Dynamic and Interactive Video Generation
- Spotlight: Lvmin Zhang | Stanford University School of Engineering