Sharan Narang
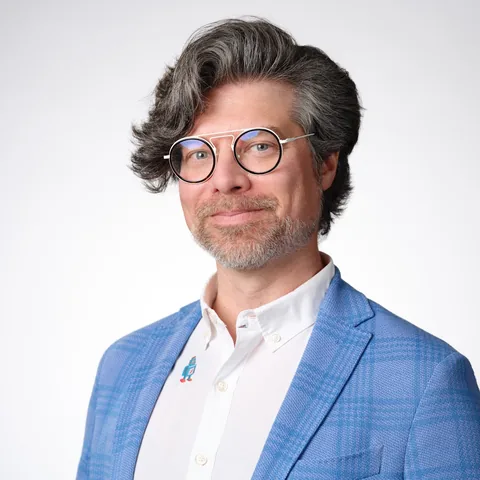
Sharan Narang is a researcher who worked on the PaLM and Llama language models at Google and Meta. After studying at the University of Mumbai and Georgia Tech and working on chips at AMD and NVIDIA, he joined Baidu in 2015, where he worked on Deep Speech 2 and coauthored the 2017 paper Mixed Precision Training. At Google from 2018 to 2022, he coauthored the T5 paper in 2019 and led work on PaLM, the 540-billion-parameter model presented in April 2022. As Director of AI Research at Meta from 2022 to 2025, he led Llama pretraining and coauthored The Llama 3 Herd of Models in 2024. Since 2025, he is a Research Director at Waymo, working on foundation and world models.
Timeline
-
2003–2009
University of Mumbai and Georgia Tech
He studies electronics and telecommunication for a BE at the University of Mumbai from 2003 to 2007. From 2007 to 2009, he is an MSc student at Georgia Tech.
-
2009–2015
Hardware engineering at AMD and NVIDIA
He works as an engineer at AMD from 2009 to 2011 and as a senior hardware engineer at NVIDIA from 2011 to 2015. At NVIDIA, he works on the Tegra SoC and the Tegra K1 CPU.
-
2015–2018
Systems researcher at Baidu
He joins Baidu in 2015 as a researcher and works on systems research, Deep Speech 2, sparse neural networks and DeepBench. Deep Speech 2, posted to arXiv in December 2015, applies end-to-end deep learning to English and Mandarin speech recognition. As a systems researcher, he focuses on faster training and inference through low-precision techniques, and in 2017 he coauthors Mixed Precision Training, which cuts memory use by nearly 2x.
-
2018–2022
Research engineer at Google
He joins Google as a research engineer in 2018 and leads work on PaLM and T5. In 2019, he coauthors the T5 paper, Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer, which converts all text-based language problems into a text-to-text format.
-
April 2022
PaLM, a 540-billion-parameter model
In April 2022, he and Aakanksha Chowdhery, both software engineers at Google Research, present the Pathways Language Model (PaLM) on the Google Research blog. PaLM is a 540-billion parameter, dense decoder-only Transformer trained with the Pathways system, and he is the second author of the paper.
-
2022–2025
Llama pretraining at Meta
He joins Meta in 2022 as Director of AI Research and leads Llama pretraining. He works on Llama 3 and Llama 4 until 2025.
-
2024
The Llama 3 herd of models
In July 2024, he is among the 559 authors of The Llama 3 Herd of Models, a set of language models that natively support multilinguality, coding, reasoning and tool usage. The largest model is a dense Transformer with 405B parameters and a context window of up to 128K tokens.
-
Since 2025
Research Director at Waymo
In 2025, he becomes Research Director at Waymo, where he works on foundation and world models.
Career
- Since 2025WaymoResearch Director
- 2022Google ResearchSoftware Engineer
- 2022–2025MetaDirector of AI Research
- 2018–2022GoogleResearch Engineer
- 2015–2018BaiduResearcher
- 2011–2015NVIDIASenior Hardware Engineer
- 2009–2011Advanced Micro DevicesEngineer
Education
- 2009Georgia Institute of TechnologyMSc
- 2007University of MumbaiBE
Videos

Video data from YouTube API Services. By watching you agree to the YouTube Terms of Service. How we use YouTube data.
Colleagues
Sources and credits
Photo: We have no published photo of Sharan Narang yet. Send us a free-licensed photo.
- Sharan Narang | alphaXiv
- Sharan Narang (@sharan0909) · Digg
- A Deep Learning Performance Lens for Low Precision Inference
- Deep Speech 2: End-to-End Speech Recognition in English and Mandarin
- Mixed Precision Training
- Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer
- Pathways Language Model (PaLM): Scaling to 540 Billion Parameters for Breakthrough Performance
- PaLM: Scaling Language Modeling with Pathways
- The Llama 3 Herd of Models
- Sharan Narang - Google Scholar