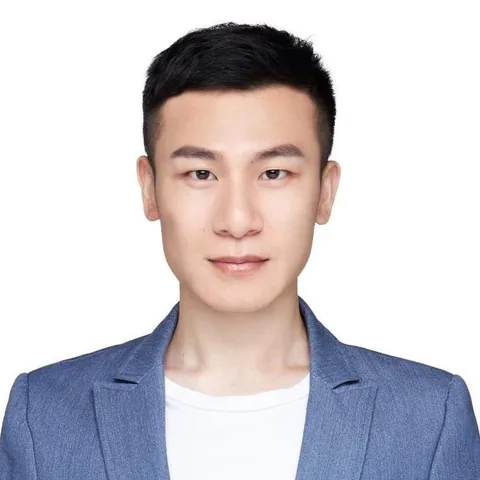
Keqin Bao
Also known as 鲍克勤
Keqin Bao is a language model researcher on Alibaba's Qwen team in Hangzhou, and his doctoral work applied large language models to recommender systems. After a computer science degree at Harbin Institute of Technology, he began a PhD in 2021 at the USTC Lab for Data Science at the University of Science and Technology of China. Early work on translation evaluation produced Alibaba-Translate China's entry to the WMT 2022 quality estimation task, which ranked first overall in two settings. As first author, he introduced TALLRec in 2023, a framework for tuning language models with recommendation data, and Decoding Matters at EMNLP 2024, a new decoding method for LLM-based recommenders. He coauthored the Qwen2.5 and Qwen3 technical reports in 2024 and 2025, then completed his PhD in 2026 and joined Qwen.
Timeline
-
2017–2021
Computer science at HIT
He studies computer science at Harbin Institute of Technology from 2017 to 2021 and earns a BEng.
-
2021
Doctoral studies at USTC
In 2021, he begins a PhD in cyberspace security at the University of Science and Technology of China, working in the USTC Lab for Data Science within the School of Cyber Science and Technology. His research moves from translation evaluation to large language models for recommendation.
-
2022
Translation quality estimation at WMT
In 2022, he is first author of Alibaba-Translate China's submission to the WMT 2022 Quality Estimation Shared Task, built on the UniTE (Unified Translation Evaluation) framework. The system ranks first overall in the multilingual and English-Russian settings.
-
2023
TALLRec for recommendation
He is first author of TALLRec, a framework that tunes large language models with recommendation data, published at the ACM Conference on Recommender Systems (RecSys) in 2023. TALLRec improves recommendation in the movie and book domains with fewer than 100 training samples and runs on a single RTX 3090 with LLaMA-7B.
-
2024
Decoding Matters at EMNLP
At EMNLP 2024, he is first author of Decoding Matters, which introduces Debiasing-Diversifying Decoding (D3) for LLM-based recommendation. The method counters amplification bias from ghost tokens and the tendency to generate similar or repetitive items for a user.
-
December 2024
The Qwen2.5 technical report
In December 2024, he coauthors the Qwen2.5 Technical Report, which describes a series of large language models whose pre-training data grows from 7 trillion to 18 trillion tokens. Hosted Qwen2.5-Turbo and Qwen2.5-Plus models are offered through Alibaba Cloud Model Studio.
-
May 2025
The Qwen3 technical report
In May 2025, he coauthors the Qwen3 Technical Report. Qwen3 joins thinking and non-thinking modes in one framework, ranges from 0.6 to 235 billion parameters, supports 119 languages and dialects, and is released under Apache 2.0.
-
Since 2026
Joining Alibaba's Qwen team
He completes his PhD at the USTC Lab for Data Science in 2026 and moves to Alibaba's Qwen team in Hangzhou. In 2026, he also coauthors MTR-Bench, a 3,600-instance benchmark for multi-turn reasoning, at the 64th Annual Meeting of the Association for Computational Linguistics.
Career
- Since 2026AlibabaLanguage model researcher
Education
- 2021Harbin Institute of TechnologyBEng
- From 2021University of Science and Technology of ChinaPhD
Colleagues
Sources and credits
Photo: We have no published photo of Keqin Bao yet. Send us a free-licensed photo.