Tri Dao
Tri Dao works on the systems that help AI models use memory and compute efficiently. His papers include the 2022 structured-matrix work Monarch and FlashAttention, followed by Mamba and a framework that connects state-space models with attention. He completed a Stanford computer science PhD in 2023, became Together AI Chief Scientist in July, and earned COLM and MLSys paper honors and a 2025 AI2050 Early Career Fellowship. As of October 2026, Dao is Together AI’s co-founder and Chief Scientist and a visiting research scholar at Princeton; the research program he leads includes FlashAttention-4.
- Now at
- Together AI and Princeton University
- Works
- 70
Publication numbers from OpenAlex, as of 14 October 2026. Citations and h-index are hidden because this OpenAlex record may be incomplete or mix in other authors.
Timeline
-
2022
Structured matrices for training
Tri Dao and his coauthors received the ICML 2022 Outstanding Paper Runner Up for Monarch, which represents common transforms with products of two block-diagonal matrices.
-
2022
Tiling attention for speed
With four coauthors, he introduced FlashAttention, an exact attention algorithm that uses tiling to reduce data movement between GPU high-bandwidth memory and on-chip SRAM.
-
2023
A Stanford doctorate
He completed a Stanford computer science PhD in 2023, co-advised by Christopher Ré and Stefano Ermon.
-
July 2023
Joining Together AI
Together AI announced him as Chief Scientist in July 2023; he joined to make open-source AI more accessible and cost-competitive.
-
2023–2024
A model for long sequences
With Albert Gu, he co-authored Mamba, a selective state-space model designed for linear-time sequence modeling.
-
2024–2025
Connecting state spaces and attention
The 2024 paper Transformers are SSMs, co-authored with Albert Gu, connects state-space models with variants of attention. His work received COLM’s 2024 Outstanding Paper award and an MLSys 2025 Outstanding Paper Honorable Mention.
-
2025
An AI2050 fellowship
Schmidt Sciences named him a 2025 AI2050 Early Career Fellow for a project that uses compilers and simulators to help AI learn through experimentation.
-
As of October 2026
Research at Together AI
He is a visiting research scholar at Princeton and a co-founder and Chief Scientist of Together AI. The research program he leads introduced FlashAttention-4, a new algorithm and kernel co-design tuned for NVIDIA Blackwell GPUs.
Sources and credits
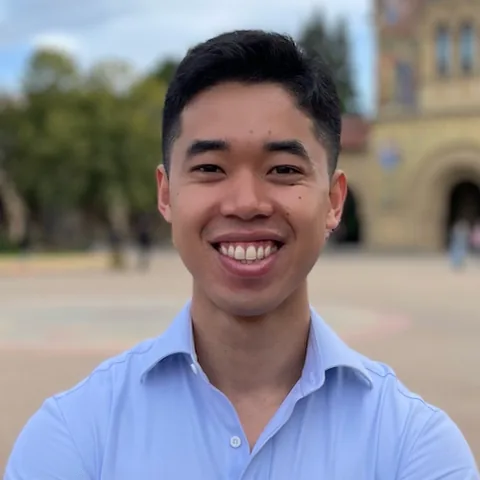
Photo: tridao.me; Tri Dao; creator not stated. License: Not stated by source. Source: tridao.me. Cropped to a square and resized. Ask us to remove or replace this photo.
- ICML 2022 Awards
- [2205.14135] FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness
- Introducing Together AI Chief Scientist Tri Dao, as he releases FlashAttention-2 to speed up model training and inference
- Tri Dao
- [2312.00752] Mamba: Linear-Time Sequence Modeling with Selective State Spaces
- [2405.21060] Transformers are SSMs: Generalized Models and Efficient Algorithms Through Structured State Space Duality
- Tri Dao - AI2050
- Inside the Together AI kernels team
- Key research and product announcements at the AI Native Conf