Jan Leike
Jan Leike leads Anthropic's Alignment Science team. His doctorate studied general reinforcement learning under Marcus Hutter. At DeepMind, he worked on alignment and learning from human feedback. A 2017 paper with colleagues tested how people's comparisons could guide behavior in games and simulated movement. He later coauthored InstructGPT and co-led OpenAI's Superalignment effort with Ilya Sutskever. That project aimed to study supervision of systems more capable than humans. At Anthropic, his work includes weak-to-strong generalization and automated alignment research. A 2026 team study reports both experimental gains and difficulties transferring results to production scale. These experiments provide evidence about specific methods and leave broader control questions open.
Timeline
-
2016
Studying learning in general environments
Leike’s doctoral thesis, supervised by Marcus Hutter, studies general reinforcement learning.
-
2017
Publishing preference-based learning
With Paul Christiano, Tom Brown, Miljan Martic, Shane Legg and Dario Amodei, Leike publishes experiments using human preferences.
-
2022
Bringing the method to language
Leike co-authors the InstructGPT paper with a large team.
-
July 2023
A harder supervision problem
OpenAI announces Superalignment, co-led by Leike and Ilya Sutskever.
-
2026–today
Studying automated research
Leike co-authors Anthropic’s Automated Weak-to-Strong Researcher study.
Sources and credits
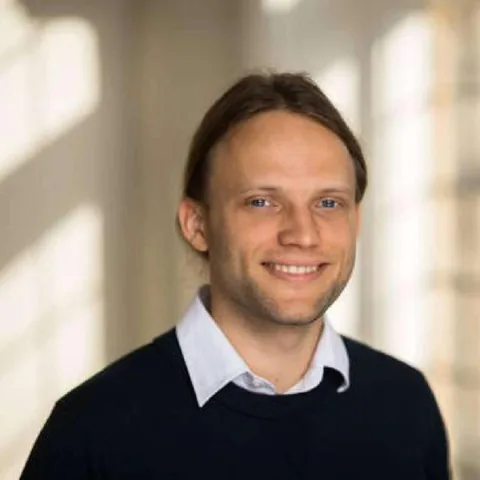
Photo: 80,000 Hours; Jan Leike interview portrait. License: Not stated by source. Source: 80000hours.org. Cropped to a square and resized. Ask us to remove or replace this photo.
- Jan Leike: current personal research page
- Leike: Nonparametric General Reinforcement Learning, 2016
- Christiano and colleagues: human preferences, 2017
- Ouyang and colleagues: InstructGPT, 2022
- OpenAI: Introducing Superalignment, July 2023
- OpenAI: weak-to-strong generalization, December 2023
- Anthropic: Automated Weak-to-Strong Researcher, 2026