Hermann Ney
Hermann Ney develops statistical and machine learning approaches to speech recognition and machine translation. Ney used dynamic programming beam search for large-vocabulary speech recognition in 1990. The approach used a lexical prefix tree to construct the search space dynamically. His work included Kneser–Ney smoothing for language modelling in 1995. The method was a shared research contribution.
- Now at
- RWTH Aachen University
- Works
- 1,452
- Citations
- 47,651
- h-index
- 93
Publication numbers from OpenAlex, as of 14 October 2026.
Timeline
-
1990
Search for speech recognition
Ney used dynamic programming beam search for large-vocabulary speech recognition in 1990. The approach used a lexical prefix tree to construct the search space dynamically.
-
1995
Language model smoothing
His work included Kneser–Ney smoothing for language modelling in 1995. The method was a shared research contribution.
-
1999
Phrase-based translation
Ney and his team worked on data-driven translation with bilingual word groups. He worked on this contribution in 1999, connecting it with the phrase-based approach to machine translation.
-
2001
A word alignment toolkit
His work included the GIZA++ toolkit, which became public in 2001. The shared toolkit trains statistical word alignments for machine translation and made this research infrastructure available to other teams.
-
2020
Research recognition
ACL elected Hermann Ney as a Fellow in 2020.
Sources and credits
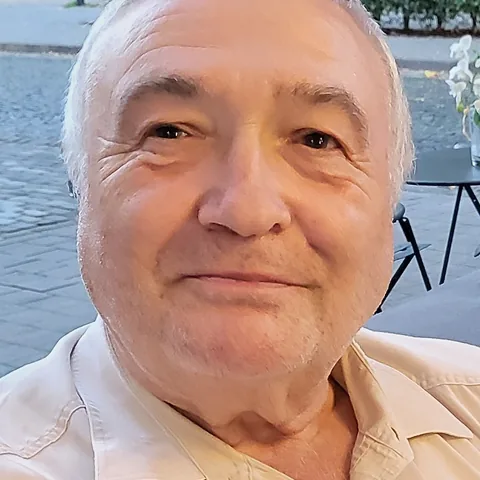
Photo: Cairnlee, via Wikimedia Commons. License: CC BY-SA 4.0. Source: commons.wikimedia.org. Cropped to a square and resized. Ask us to remove or replace this photo.
