Devi Parikh
Also known as Dev Parikh
Devi Parikh is an AI researcher whose work spans computer vision, visual question answering, and generative models. After engineering degrees at Rowan University and Carnegie Mellon, she held research and faculty posts at TTIC and Virginia Tech before joining Georgia Tech and Meta. Her projects include Relative Attributes, VQA, Make-A-Video, and Emu Video. She received the 2017 IJCAI Computers and Thought Award, and the VQA Series of Challenges received the 2025 Mark Everingham Prize. She is now co-founder and co-CEO of Yutori, where her team is building AI assistants for web tasks.
- Now at
- Yutori
- Works
- 309
- Citations
- 62,898
- h-index
- 77
Publication numbers from OpenAlex, as of 14 October 2026.
Timeline
-
2005–2009
An engineering education
She earns a B.S. from Rowan University in 2005, then an M.S. from Carnegie Mellon in 2007 and a Ph.D. there in 2009.
-
2009–2016
From Chicago to Virginia
She is a Research Assistant Professor at TTIC from 2009 to 2012, then an Assistant Professor at Virginia Tech from 2013 to 2016.
-
2011
A Marr Prize for relative attributes
Her paper “Relative Attributes,” coauthored with Kristen Grauman, received the Marr Prize at ICCV.
-
2015–2017
Teaching machines to answer
“VQA: Visual Question Answering” introduces a task for open-ended, natural-language answers to questions about images. IJCAI named her the 2017 Computers and Thought Award winner for contributions at the intersection of words, pictures, and common sense.
-
2016–2024
Holding two research posts
In 2016, she joins Meta’s FAIR lab and Georgia Tech’s School of Interactive Computing. She leaves the Georgia Tech professorship in 2024.
-
2022–March 2024
Generating video from prompts
While serving as a Senior Director in Generative AI at Meta through March 2024, she coauthored Make-A-Video and Emu Video. Make-A-Video adapts text-to-image generation for video using unsupervised footage; Emu Video generates a text-conditioned image first, then conditions video generation on that image and text.
-
2025
A prize for the VQA challenges
The VQA Series of Challenges, with Parikh among its contributors, received the 2025 PAMI Mark Everingham Prize for stimulating a new strand of vision-and-language research.
-
As of October 2026
Building agents for the web
At Yutori, she is co-founder and co-CEO. The team builds browser and computer-use agents for everyday digital tasks through an agent-first approach with specialized post-training, reinforcement learning, test-time search, and multi-agent collaboration.
Sources and credits
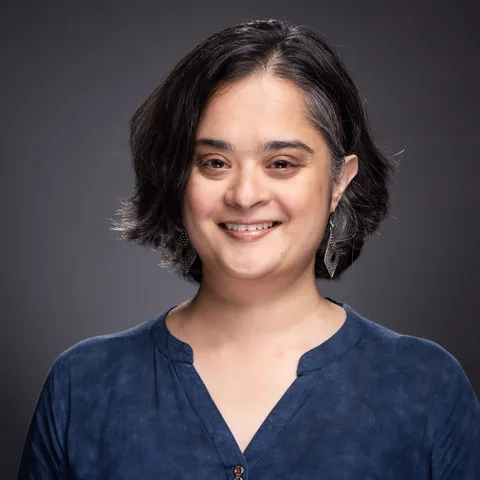
Photo: deviparikh.com; Devi Parikh; creator not stated. License: Not stated by source. Source: deviparikh.com. Cropped to a square and resized. Ask us to remove or replace this photo.
- Devi Parikh
- Devi Parikh | Institute for People and Technology
- Kristen Grauman Awarded The Marr Prize | UT Austin Computer Science
- [1505.00468] VQA: Visual Question Answering
- Welcome to IJCAI 2017!
- Devi Parikh
- [2209.14792] Make-A-Video: Text-to-Video Generation without Text-Video Data
- [2311.10709] Emu Video: Factorizing Text-to-Video Generation by Explicit Image Conditioning
- VQA: Visual Question Answering
- Announcing Yutori's mission and Seed funding round
- Company - Yutori - Browser-use and computer-use AI agents